



A marketing data pipeline is an automated system that collects marketing data from your marketing platforms, transforms it into a consistent format and delivers it to a central warehouse, BI tool or activation platform for your team to analyze or act on.
The allure of building custom, in-house marketing data pipelines can be compelling for many organizations. From a zoomed-out perspective, it promises greater control, the ability to customize to specific needs, centralization of data and upfront cost savings.
However, while these benefits are theoretically attainable, building a pipeline in-house also means you own every single failure point along the way. You’ll need the skills and resources to keep trustworthy data flowing where it needs to go; otherwise, you could end up with complex pipelines and time wasted managing infrastructure.
So, should you build a pipeline in-house? Let's delve into the main challenges a data engineer will encounter in the setup and maintenance of in-house marketing data pipelines and what to consider before you start building.
A decision framework for building marketing data pipelines
Building an internal, robust data pipeline requires evaluating four factors: data requirements, data storage locations, system ownership and compliance rules.
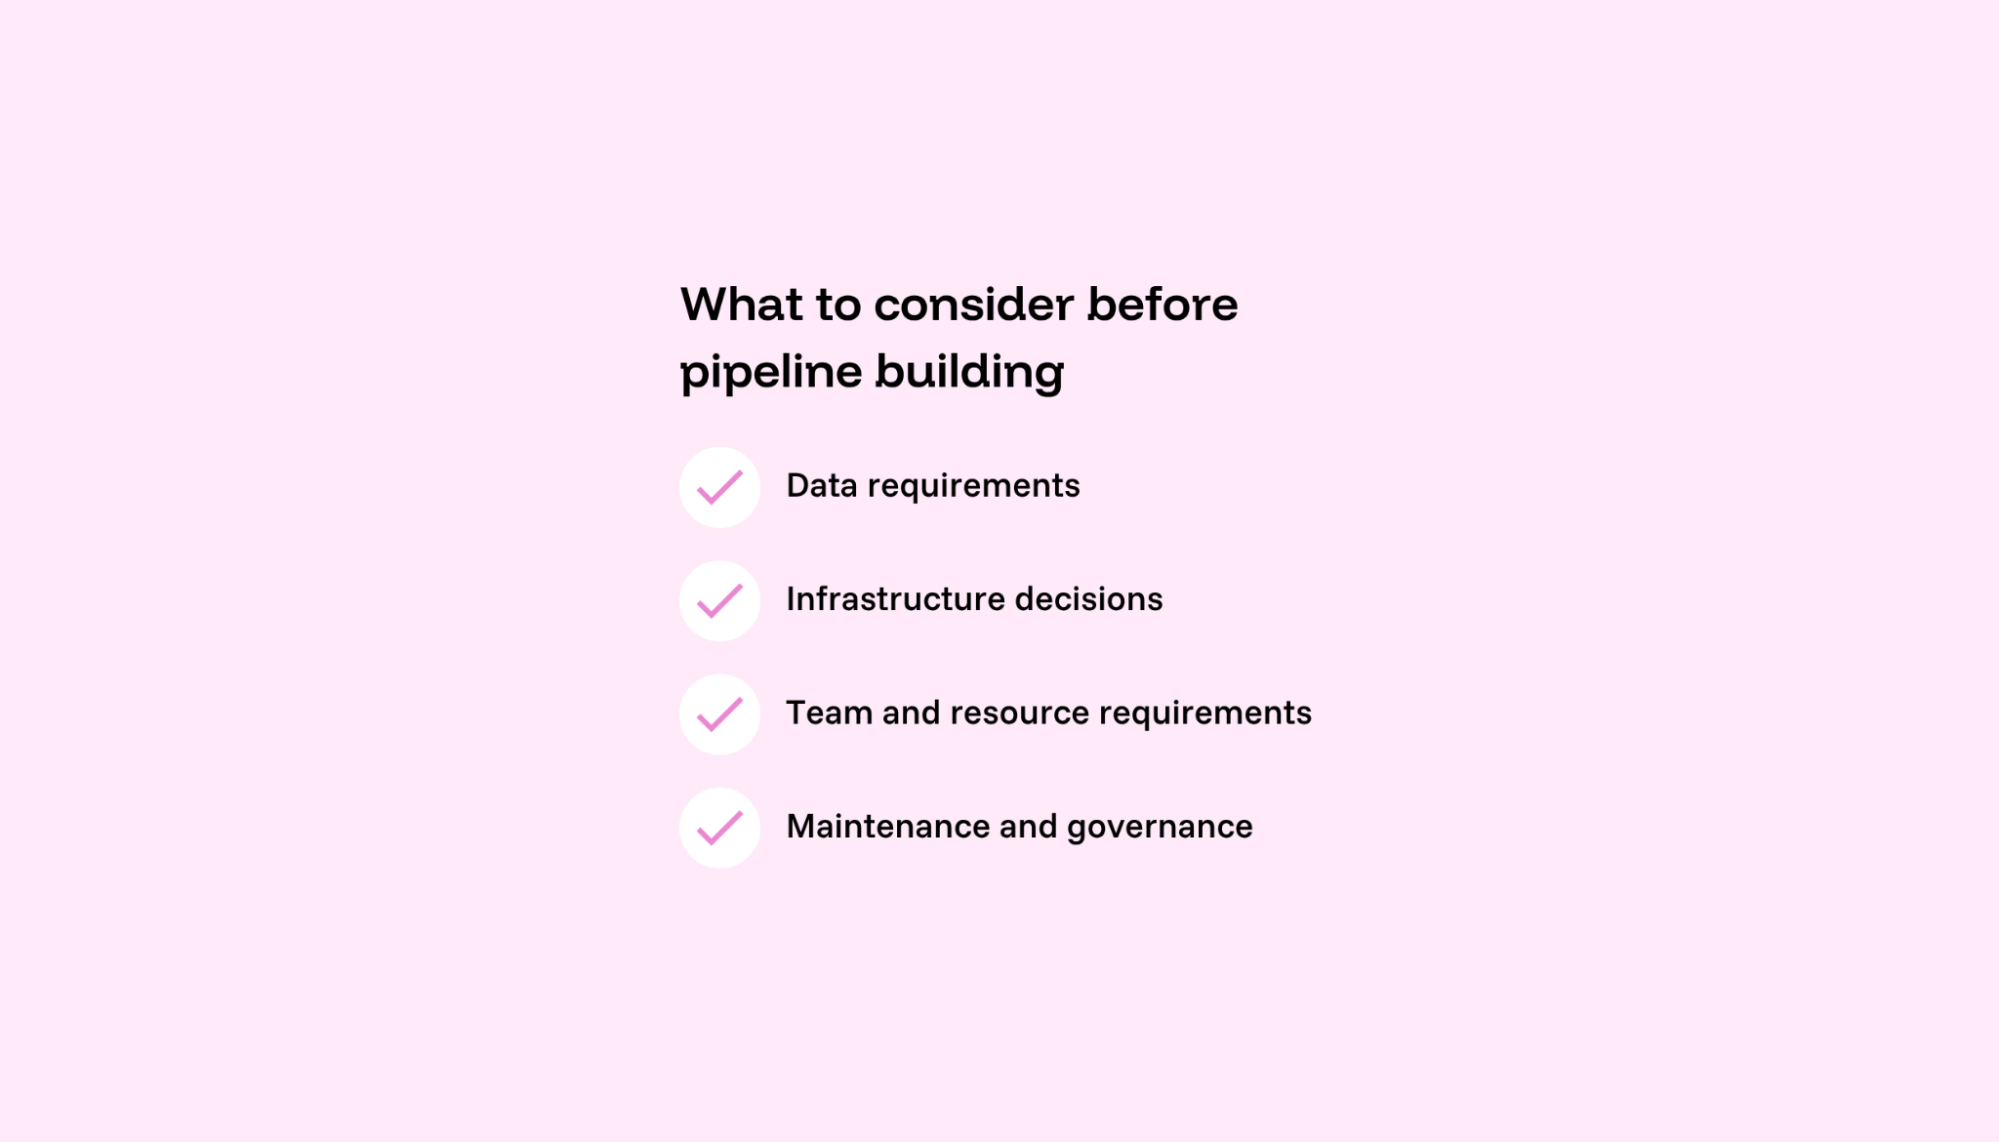
If you overlook any of these factors, it may lead to unexpected engineering costs later because each one alters the software architecture you have to build.
Data requirements
Your data choices dictate the size and cost of the pipeline. You must define your data sources and how often you need to pull updates. Your pipeline architecture also depends on the detail required for your data volume, for example, simple daily campaign totals or massive row-by-row click logs.
Setting up API connections
The foundation of a pipeline build is the API connections. The scope might range from just a few to tens of different platforms, and it could span many accounts per platform, depending on your business size and marketing setup.
After the platforms and accounts have been mapped out, consider the level of granularity you need. Very basic reports containing campaign, costs, clicks, and impressions data are usually straightforward, but if there are additional requirements (like conversion data, geographical data, demographical data, and so on), you might need to piece together results from multiple API calls.
Meta Ads is an example of an API that can be challenging to work with, even for experienced data engineers. Building the initial integration is a reasonable task for most data engineers, but maintaining a steady pipeline is the challenge. Quota and rate limits need to be considered. And when data fetches fail, there needs to be a mechanism for retries.
Data mapping
Marketing data is largely heterogeneous, but there are commonalities across different platforms that often provide value when they are mapped together. Cost, clicks, and impressions are basic examples of metrics that exist in most types of marketing platforms. Mapping them together produces a holistic overview of marketing efforts.
Depending on the number of platforms and ad accounts you have, harmonizing a metric like 'clicks' across platforms is usually straightforward. However, more advanced challenges can involve splitting out campaign name structures to allow granular reporting across platforms.
Currency conversion
For global businesses, dealing with multiple currencies is standard, yet cumbersome. Implementing reliable and up-to-date currency conversion processes ensures that financial metrics are always accurate and comparable. This is another challenge that becomes exponentially more challenging the more currencies that are involved
Data quality for AI
According to a report by McKinsey, agentic systems in marketing will accelerate campaign creation and execution by 10 to 15 times. But without a reliable data foundation, marketing teams might find they’re losing just as much time as AI promised to save in cleaning up messes and fixing downstream problems.
Machine learning models and agentic AI workflows depend entirely on data accuracy and consistency, as the algorithms require uniform data inputs to function properly. If you feed your models inconsistent text formats, gaps in your historical records or unmapped tracking codes, you’ll end up with distorted outputs. If you put garbage in, you’ll get garbage out.
A marketing data pipeline that is ready for AI needs a unified, governed data foundation, a flexible infrastructure and reliable APIs for data ingestion and activation. It should also store historical data so you can ensure your dataset is complete.
Infrastructure decisions for cloud data pipelines
Next, you need to define your data requirements, which allows you to choose where to process your pipeline and where to store your final output. Your marketing data stack relies on a connected chain of separate software tools, which introduces technical risk because you encounter data format errors during transfer points between platforms. If you build a custom internal pipeline, your team must manually configure server capacity, monitor API uptime and pay for the cloud costs associated with transforming data.
Navigating API documentation
The front-end UI and back-end of marketing platforms tend to look very different, because they are generally developed and maintained by different teams on the platform side. This means that it can be challenging to understand how to translate a request from the marketing team (which is based on the UI) into what type of API call is needed to retrieve data from the backend.
Managing data endpoints
Once data is fetched, cleaned and structured, it often needs to be sent to various tools for analysis, visualization or storage. Efficiently managing these transfers while ensuring data integrity is essential.
Building new API connections
As marketing efforts expand, new platforms and tools come into play. The ability to rapidly integrate new API connections ensures the pipeline remains relevant and comprehensive.
Centralized data warehouse
A centralized database setup places a cloud data warehouse, such as Google BigQuery, Snowflake or Databricks, at the foundation of your system, and then connects specialized tools to handle data collection, cleanup and analysis. A modular approach like this trades the simplicity of a single platform for absolute operational flexibility, meaning you own the connections between tools.
However, every additional tool adds to your software bill, can increase data delays and creates another system for your team to maintain, so weigh that overhead against your need for flexibility before you commit.
A centralized design with a marketing intelligence platform like Funnel keeps your raw data intact and applies the cleanup rules when you run a report. That way, your historical records stay safe if business definitions change down the line.
Reverse ETL
A data pipeline that only collects information solves only half of your problem. You also need to push your structured, normalized data back out to the operational tools where your daily work happens, like your ad networks, CRM systems and email platforms. This process, reverse ETL, moves your governed warehouse data backward into your marketing apps.
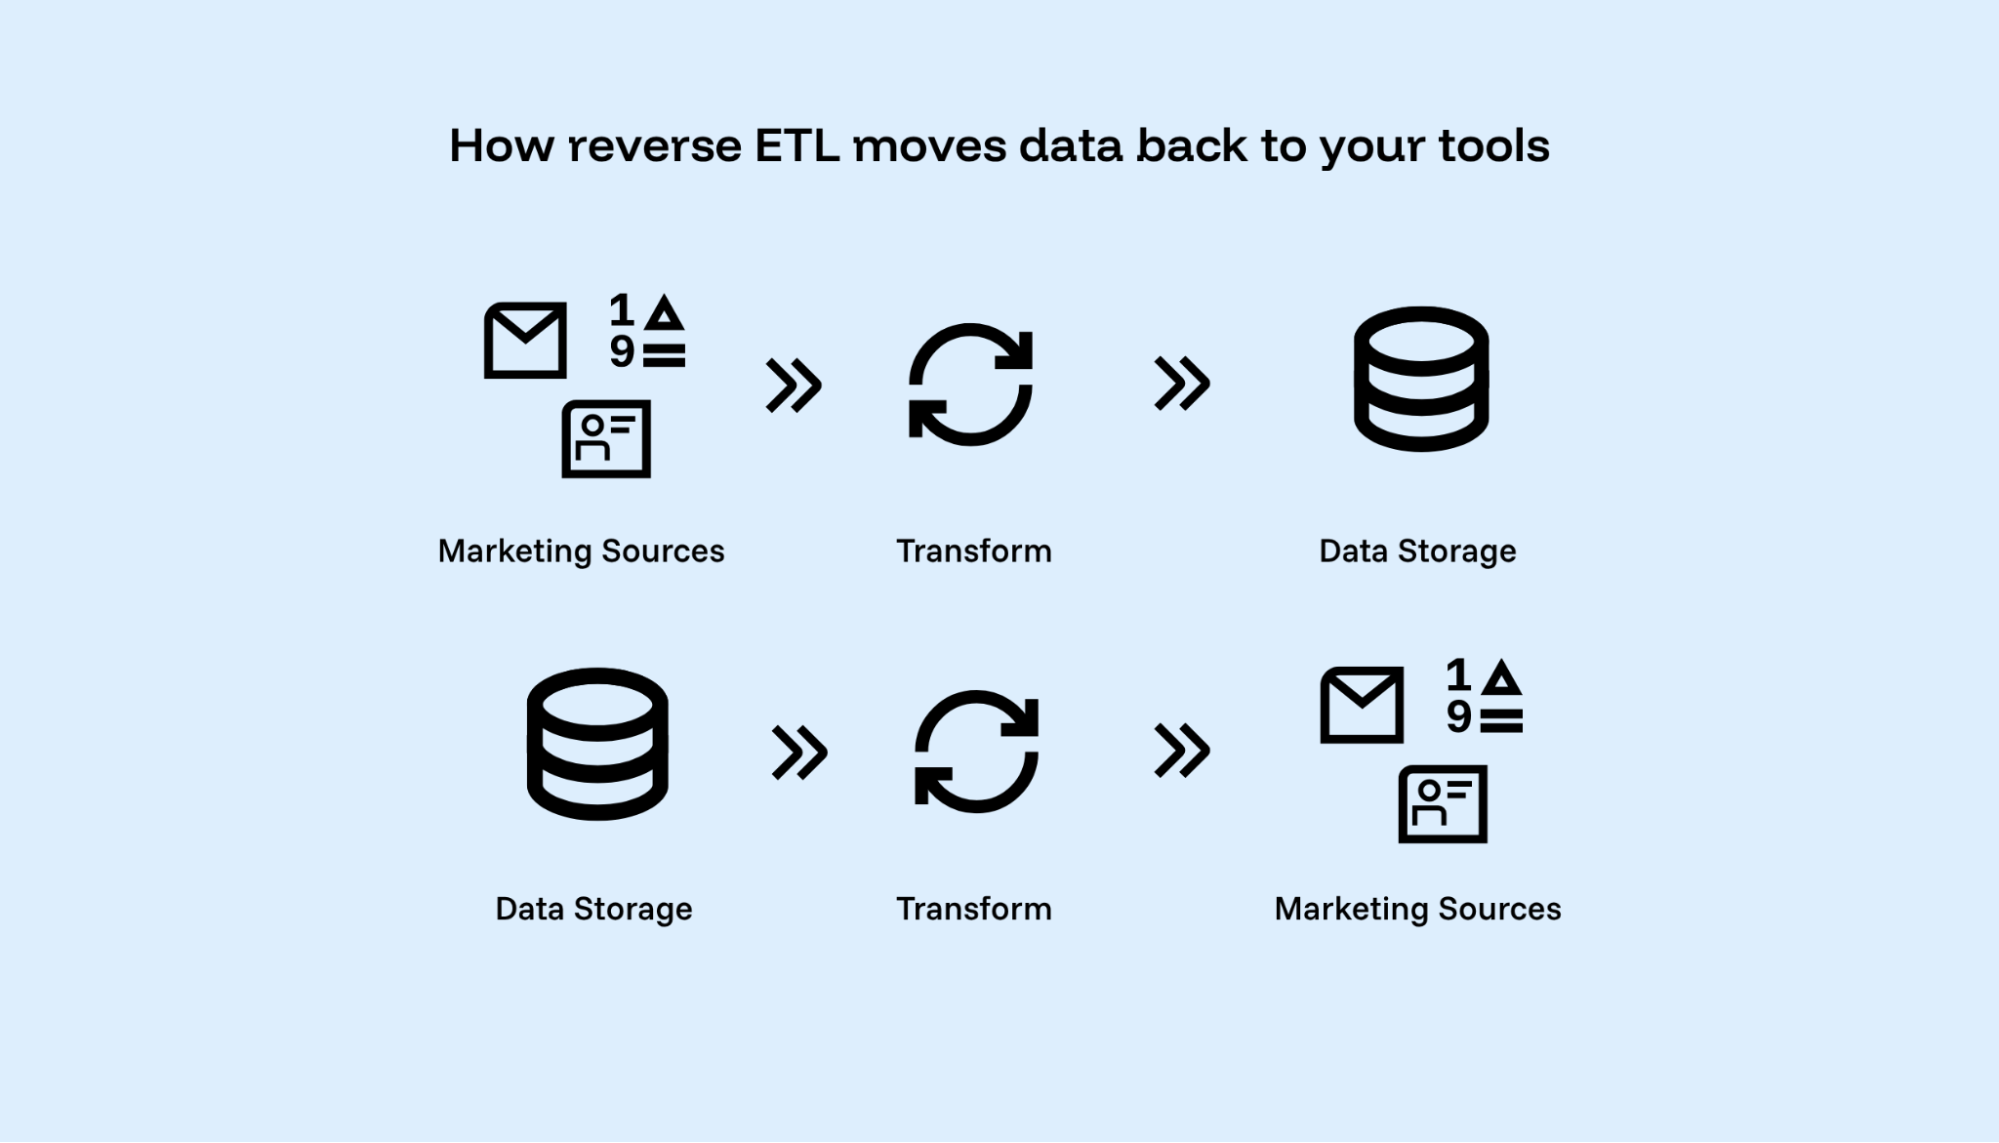
For marketers, the most common task is to send first-party customer purchase data back to ad platforms, like Meta and Google Ads, which feeds real sales outcomes into their ad algorithms to optimize ad spend. Platforms like Funnel directly manage this type of data activation by pushing secure, privacy-compliant conversion signals straight to ad network APIs.
Team and resource requirements for data analytics
Your data pipeline is only as reliable as the team you assign to support it. While the financial cost of building a pipeline is pretty transparent, the maintenance cost isn’t as easy to forecast. What happens is it drains time from your most expensive engineering talent. For example, if an ad platform updates its API, your data connectors might break, requiring your team to drop their analytical work to fix them.
Budgeting time and resources for maintenance
Larger APIs tend to update to a new version on roughly a quarterly basis. With each new API update, several fields are added, deprecated, renamed or recategorized. Depending on how exposed you are to these changes, it will incur hours or weeks of work for your data engineers to have everything functioning as expected. It can also lead to new field requests from end users.
Stakeholder management and data analysis
Stakeholder management involves identifying, understanding and effectively engaging with your marketing team and executives who rely on the output of what is being built. Depending on the size and geographical distribution of your team, the time it takes to align might range from a few hours every month to regular check-ins every week.
Data governance and ownership
A single data engineer can build the launch version of your pipeline, but you’ll need a plan for long-term system upkeep as the developers who built your original system eventually change jobs. Decide who owns the pipeline long term before you begin construction, because the designated owner will pay for any technical shortcut you take today.
Post-launch maintenance and governance
A well-built data pipeline requires constant data monitoring, rapid error correction and strict data security rules because each protection is far more difficult to integrate later down the line when the team is under operational pressure.
Scheduling and handling retroactive data updates
Marketing data is dynamic. This means that values are expected to change as time progresses, and this needs to be considered for each platform that is integrated. On top of scheduling regular data refreshes, these also need to include a mechanism to handle instances where data is updated retroactively (i.e., re-downloading and updating existing data periodically). This ensures data consistency and accuracy over time.
Error and quota management
Errors are inevitable. A robust system should be in place to handle errors, perform retries and implement backoffs, and always respect rate limits and quotas set by platforms. This prevents overloading systems and safeguards against potential data loss. If these are not calibrated correctly, it can cause significant disruptions to data pipelines.
Non-communicated API changes
Platforms often communicate API changes at the same time as they are rolled out. Proactive monitoring and rapid response mechanisms are essential to avoid protracted data interruptions.
Security: Access tokens and credential management
Ensuring that access tokens, credentials and other sensitive data are securely stored and managed is non-negotiable. Furthermore, API access is usually coupled with working credentials for the platform in question, which means that when team members lose access (as in the case when a person leaves the company), credentials need to be rotated to new working ones so as not to lose data access.
Building support for new connectors, reports and fields
With evolving business needs, the type of insights required will change. Similarly, new marketing platforms pop up regularly, and existing platforms evolve and expand their offering. These new opportunities generate data, which, in turn, is made available via the respective API’s. This requires either building support for new connectors or adding fields and reports to existing ones. For most marketing teams, these are frequent occurrences. In order to keep the marketing team working quickly, the data integration needs to follow suit, but it’s easy for requests to pile up as a ticket backlog.
Data integration governance and compliance
Data governance determines who can access your database, how you define key performance metrics, where your information originates and how you prove compliance with privacy laws like GDPR and CCPA. If you treat compliance as a future project, you’ll have to reverse-engineer your protections under the pressure of an official audit.
Build access controls and have transparent data history tracking in your pipeline from day one. Platforms like Funnel operate exclusively with privacy-safe, non-personal data, which keeps your compliance requirements more manageable from the start.
The build vs. buy decision for reliable data pipelines
Evaluating the framework categories (data requirements, infrastructure, team capabilities and governance) provides a realistic picture of what modern data pipelines will cost to build and maintain over several years.
Every factor in the framework requires a recurring budget rather than a one-time setup fee, and these ongoing costs will influence your final choice on whether you build or buy your pipeline. If you build your own pipeline, you secure total control and the freedom to handle unique tracking exceptions that a pre-built tool might miss. But if you buy a platform, you trade absolute customization for managed connectors that stay up to date, maintenance tasks handled by someone else and a much faster path to usable data.
Ultimately, your final decision depends on how specialized your marketing needs are and how much engineering time your team can spare for projects that directly grow the business.
Cost-benefit analysis: Is building in-house marketing data pipelines worth it?
As we've explored, the intricacies of marketing data present both unique challenges and ongoing commitments. Yes, with a talented data engineering team and sufficient time, an in-house solution can be crafted. ETL tools like Airbyte, Supermetrics and Fivetran make the initial setup feasible. But it's important to understand that getting data into the data warehouse is a relatively small feat. The real value lies in what you are able to do, and spend time on, after the data is there.
Considering recurring tasks and the potential for unexpected issues, it's crucial to ask yourself: "Is the ongoing investment of your data engineering time the best way to achieve efficient, error-free, and comprehensive marketing data management?"
Remember, data engineers are a premium asset. This asset, alongside potential data scientists and analysts, should be used for activities that generate business value. Balancing their workload and expertise against the recurring demands of maintaining marketing data pipelines can be a challenge in itself.
Why Funnel is the game-changer for data engineers
Enter Funnel: the platform built to streamline the complexities of marketing data management. The marketing data hub acts as your copilot, ensuring that all of the hangups associated with self-built data pipes are avoided.
Its 600+ connections are managed by our team, ensuring they remain up-to-date with the latest platform requirements. Plus, Funnel’s integrations and no-code approach make it easy for engineers, marketers and business teams to work harmoniously.
Funnel is a marketing intelligence platform made to give teams a trustworthy data foundation to use for reporting, measurement, AI workflows and other marketing use cases.
FAQs
What is a marketing data pipeline?
A marketing data pipeline collects data from your ad platforms, web analytics tools and other sources, cleans it and delivers it to a central storage database or data visualization dashboard. A pipeline replaces the manual exports and spreadsheet chores that break the moment you add a new marketing channel.
Should I build or buy a marketing data pipeline to process data?
Choose a custom build if your data requirements are highly specialized and you have the permanent engineering staff to maintain the system for years. Buy a platform if you want data connectors that stay up to date without internal upkeep, because the long-term maintenance burden of API updates and compliance rules outweighs the control a custom build provides.
What data sources should a marketing data pipeline include?
Ideally, your pipeline should ingest all the marketing data you want to store in a warehouse or data hub, use for reporting or analysis, activate or feed into AI and measurement models, so your sources include your ad platforms, email, CRM, social, search, tracking apps and marketplaces.
How do I know if my data processing pipeline works correctly?
A healthy pipeline delivers data that’s complete and consistent from all sources. You can assess your current system using our guide on data reliability.
What is the difference between ETL and a marketing data pipeline?
ETL (Extract, Transform, Load) is the process of extracting data from sources, transforming it and loading it into a warehouse, data lake or BI tool. A marketing data pipeline is built specifically for marketing data.
What is data ingestion in a marketing data pipeline?
Data ingestion is the first stage of the pipeline: it’s the process of extracting data from your ad platforms, search tools and CRMs into the system before any transformation.